


The rapid and growing emergence of digital technologies and associated data processing techniques has led specialists from various fields to ask themselves that question.
Currently, our personal data constitutes a formidable source of economic resources for those who own it and know how to use it.
Knowing behavior and consumption patterns allows a huge variety of companies to better target and price discriminate the target audience to which they seek to offer their products.
But that's not all, the use of this type of technology allows us to go even further, by enabling the possibility of modifying behavioral patterns; for example, creating ads and incentives focused on the audience of interest, or using keywords that serve as specific deterrents for each group of people.
Or also, through the creation of credit scoring systems, such as Alipay 's Zhima Credit system . And the cases continue.
If the scenario – already complex – were to regulate, in favor of a certain notion of the common good, the relationships established between private organizations and individuals, the role of the State would have an ambitious, but defined, objective.
The problem is that these types of tools can easily be adapted to influence the behavior of citizens at the level of decisions at the economic level, but also at the political and social level. Which represents an enormous challenge for any modern democracy, which, by definition, is a government of opinion.
For example, during 2019 there has been extensive debate about the decisive role that the use of big data techniques had in the outcome of Brexit; as well as the pilot project of social credit implemented in the Chinese city of Rongcheng, a record of background in which good deeds add points, and violations of the law subtract.
Beyond the novelty in the creation and use of data, the truth is that countries with a certain level of development have been collecting statistical information about their population for several decades.
One of the virtues of this type of survey is that -generally- the aim is for the information collected to be representative of the reference population. The other is that a significant part of this information has been, since practically its inception, open access.
Representativeness is a desirable characteristic since it allows for a complete and unbiased picture; something that does not necessarily happen with the information collected in private databases (generally: the data that we voluntarily provide when we install an application on our cell phone or browse social networks).
But achieving this characteristic has a cost, and that is the deployment of resources that official statistics organizations invest in obtaining it.
Thus, the question of personal data ownership rights faces a complex and difficult-to-generalize landscape. On the one hand, some companies may have access to information about the behavior of the population in territories where the state does not collect it.
On the other hand, this information is surely biased, given that - for example - not the entire population of a territory uses the same application, but rather a subset that is not necessarily representative. The opposite happens, in some cases, with public information.
In this way, the question with which this article begins has an enormous amount of nuances, both for its good consequences: for example, better planning of public policies based on evidence; as well as those that are undesirable: for example, a systematic violation of people's privacy (or even other smaller effects, such as the publication of biased or methodologically misestimated information).
News sometimes imposes its logic. Among the demands for more and better information, citizen data initiatives and open government, regulation projects for companies that generate profits with databases, among others; Sometimes we lose sight of the use, dissemination and understanding of existing data.
The report presented in this article aims to build upon solid foundations by facilitating access to and interpretation of one of the most important surveys in our country.
In Argentina, one of the best population-level surveys available is the Permanent Household Survey . It is a national program for the systematic and ongoing production of social indicators, conducted by the National Institute of Statistics and Censuses, which provides information on the sociodemographic and socioeconomic characteristics of the population.
With the data obtained in this survey, data referring to official employment, unemployment, underemployment and poverty rates are regularly provided; among others.
EPH databases are an essential input for the reports and work carried out in our agency. However, for those who are not familiar with its operation, or only want to ask a specific question, its operation can involve a high entry cost. For example, what a motivated student in an undergraduate degree can do.
The EPH Manual – Observatory (and the corresponding databases) has sought to facilitate access to them, proposing a more intuitive use.
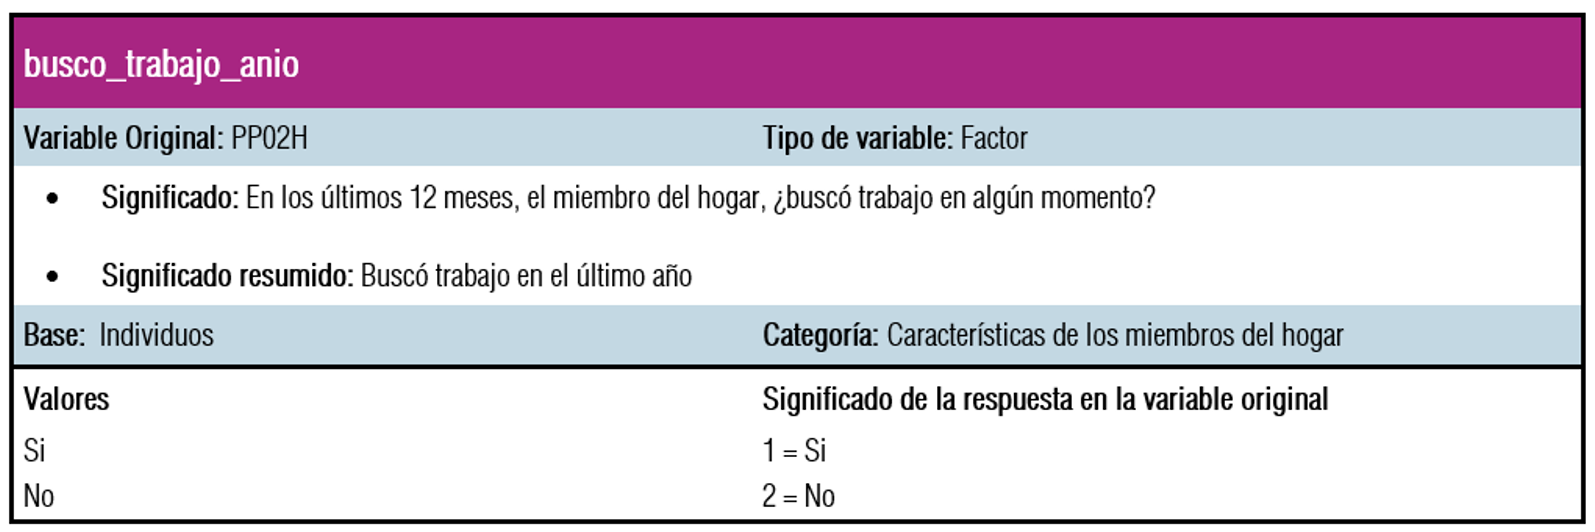
The EPH – Observatory databases are presented in RDATA format, that is, for use in the free code program R. The manual presents a sheet like the one shown in the previous image, for each variable, so that its interpretation is self-conclusive.
Each variable has been renamed with a non-coded name, and labeled so that its meaning can be read directly from the program interface. The same has been done with the internal values of each variable. Instead of presenting numbers only interpretable with the original EPH manual, the meanings of each value have also been labeled.
Likewise, new variables have been incorporated, which can be classified into three groups:
- Product of the calculation of two or more variables within the original base
- Product of the cross with data external to EPH
- Closed classifier breakdown product
The databases and manual will be available in the section dedicated to the Permanent Household Survey, as well as on the UNR Hypermedia Repository profile . Both will be updated as INDEC collects data for new quarters.
The question of who owns our data is still not resolved. However, we can invest in facilitating access to what is actually available, raising awareness about what is a desirable standard of information; and from that base, demand measures that, without inhibiting initiatives for better and more information, violate privacy and rights.
We hope with this small contribution to facilitate the work of our researchers in the broad field of social sciences, with interference in population data. Public university, always.